How We Score a Website for AI Visibility: The GeoTest Scoring Methodology
A technical overview of the six-category framework we use to measure, score, and improve a website's readiness to be cited by AI-powered search agents.
The GEO Score in short
The GEO Score is a 0 to 100 rating of how ready a page is to be quoted by AI answer engines such as ChatGPT, Perplexity and Google AI Overviews. It adds up six categories, weighted by what citation research shows those engines quote: sourced facts and answer-first structure count most (Citation Worthiness and Answer Structure carry 56% of the page score between them), word count not at all. A page whose checks cover under 75% of the expected evidence shows Insufficient coverage instead of a grade. A full site scan scores up to 200 pages; the site score is 70% the weighted page average and 30% site-level checks such as topical clusters and an About page. Every check, threshold and weight is published below, so any score can be reproduced by hand.
| Category | Points | The question it answers |
|---|---|---|
| Citation Worthiness | 34 | Does this page carry facts an answer engine can quote, and show where they came from? |
| Answer Structure | 22 | Can an engine lift a complete, self-contained answer from this page without reading all of it? |
| Authority and Trust | 17 | Can an engine tell who is behind this page, how to reach them and who vouches for them? |
| Structured Data | 12 | Is the page's meaning declared in a form a machine can read, and does it match what the page says? |
| Freshness | 7 | Can an engine date this page, and does the date hold up? |
| Extractability | 8 | Can a crawler reach the page, read its text in the first response and know which URL is the original? |
How real sites score on the rubric
Applied to real sites, the rubric is demanding, and few sites clear its top band. In the GeoTest Benchmark Report 2026, which runs to 12 pages, 4,999 US business homepages had a median of 49: 53.1% scored below 50 and not one earned an A, with Answer Structure earning 31.1% of its points and Citation Worthiness 26.6%. In the live benchmark, only 2 of 5,714 sites scored 90 or more as of 24 October 2026. Our own site scored 93, grade A, across 40 pages on 26 October 2026; rewriting the first sentence under each heading on 29 of its 37 pages had taken it from 83 to 93 in a day. A Quick Scan takes about 15 seconds (the average was 11 seconds across 565 production scans from 5 September to 5 October 2026), a Site Analysis usually 1 to 3 minutes, and Agency Plus raises the crawl ceiling to 400 pages.
See the rubric applied
Every rule below is applied to our own site: the score, each issue priced in points, and the fix written from our own pages. Not just a score: the fix.
Open our live report →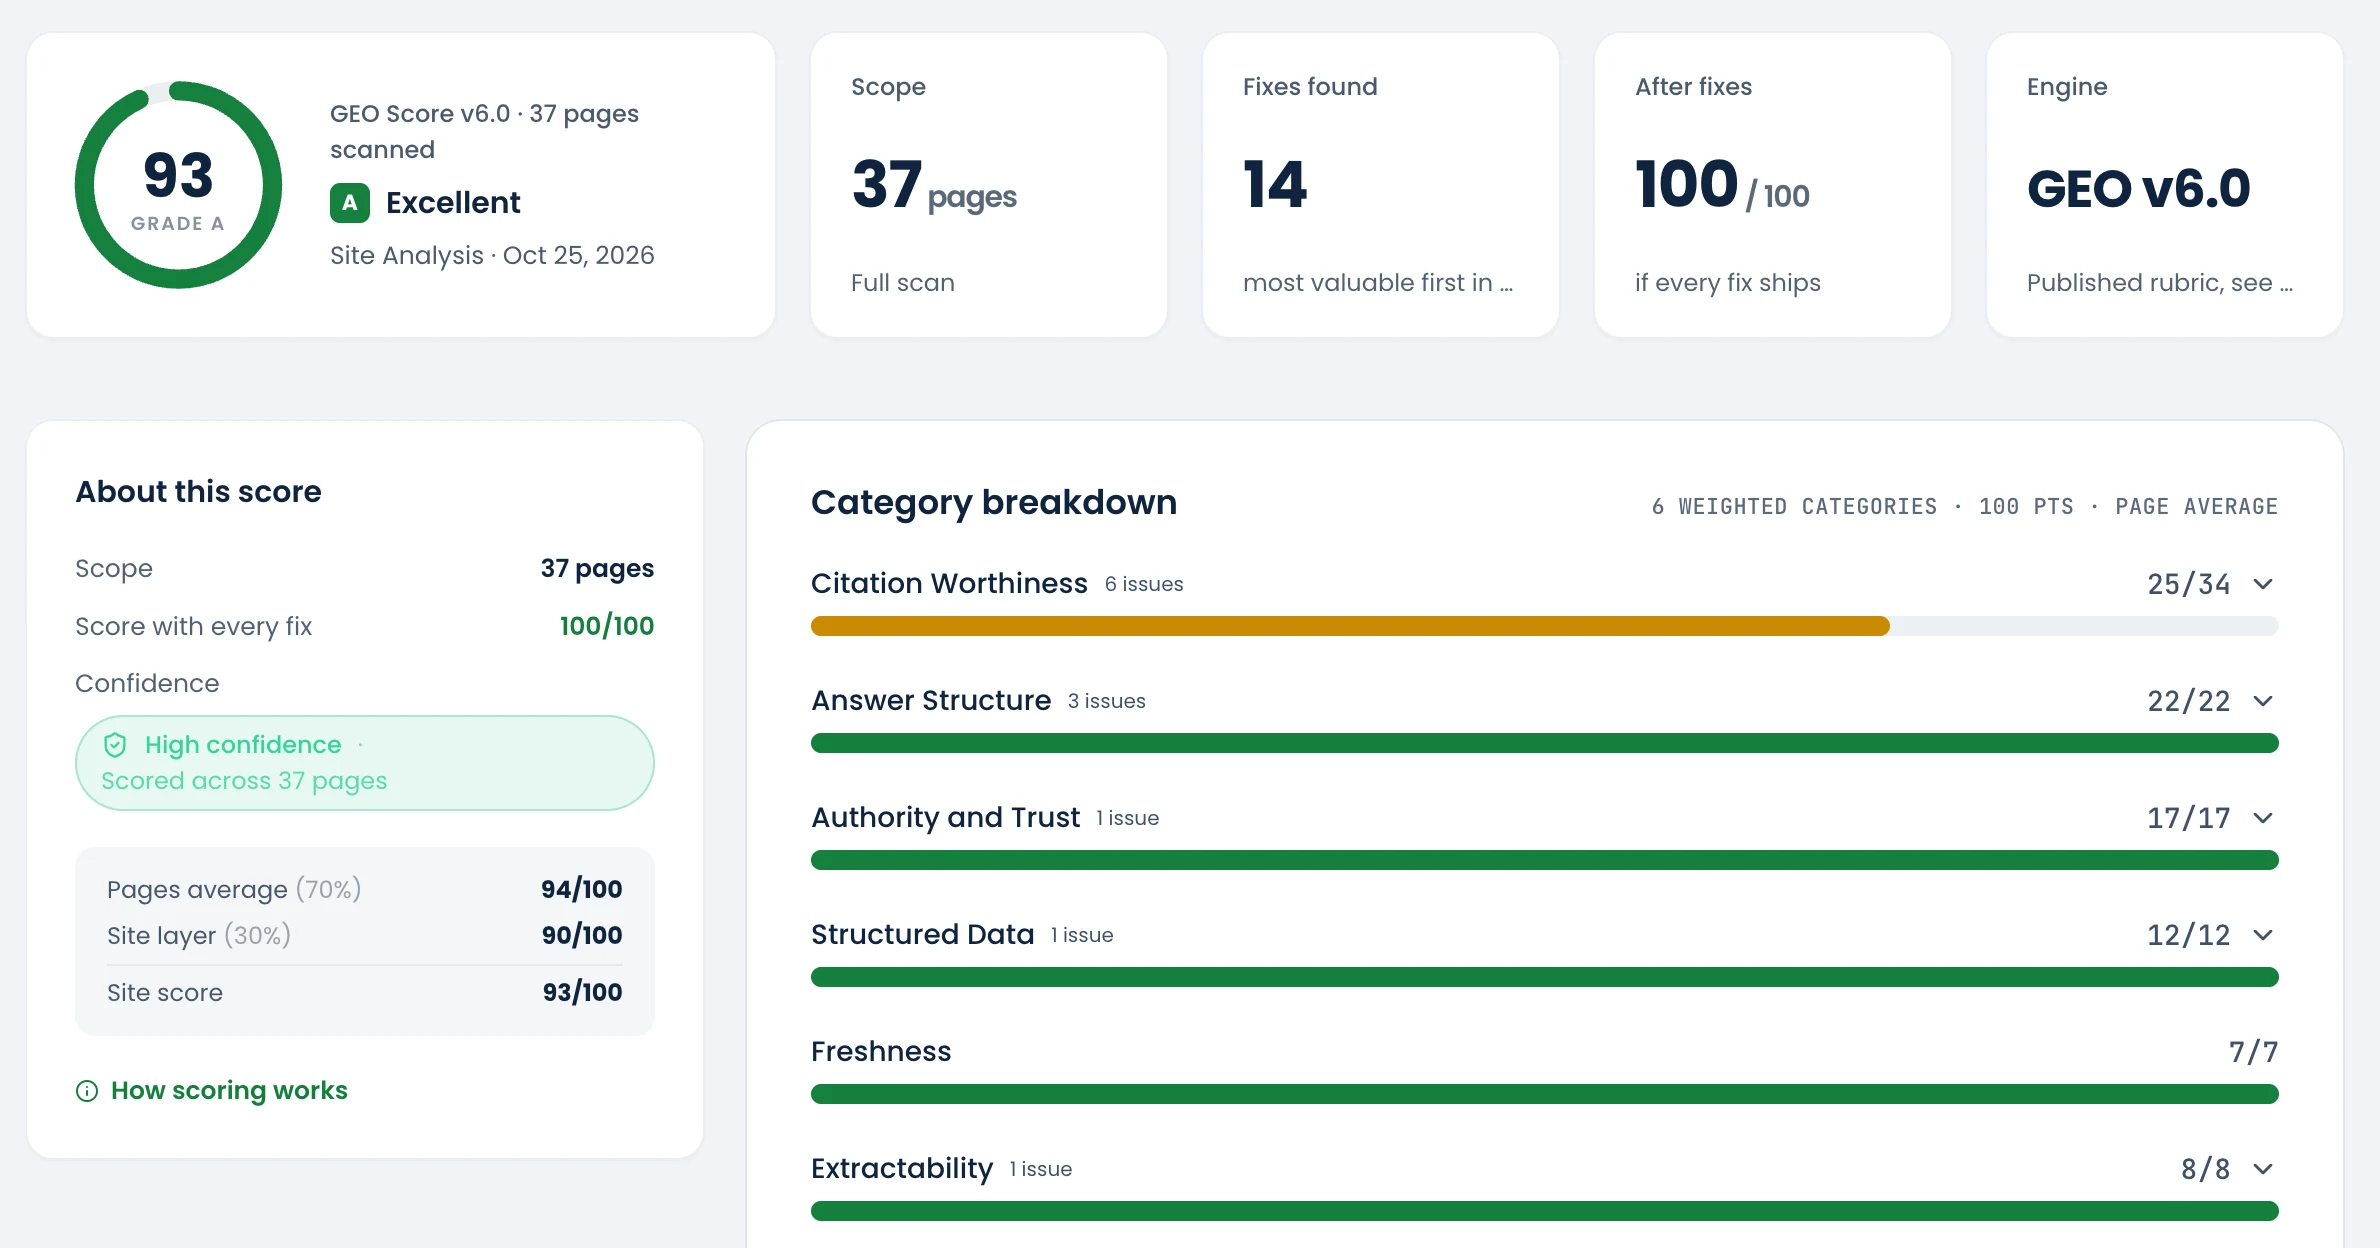
Abstract: from search rankings to AI citations
Traditional search engine optimization (SEO) produced a well-understood set of signals: backlinks, keyword density, page authority, Core Web Vitals. Over two decades, the industry built reliable methods to measure and improve these signals because the target - a ranked position on a results page - was observable and consistent.
Generative Engine Optimization (GEO) requires a different measurement framework entirely. When the output of a search interaction is a synthesized paragraph rather than a list of ranked links, the signals that predict success change fundamentally. A page can rank #1 on Google and still never be cited in an AI-generated answer. Conversely, a page ranked on page two can become a primary AI citation source if its content is structured correctly.
This document describes the GeoTest Scoring Engine v6.0 - the scoring framework we built and now use as the analytical foundation for every GEO engagement at SpecLoop. It covers what we measure, how we measure it, why each category was included, and what the resulting scores mean in practice.
This document also publishes the exact category weights used by the engine. We've chosen full transparency over proprietary obscurity: the scoring contract is open, the categories are open, and the rubric below mirrors the production code in supabase/functions/_shared/scoring/scoring-contract-v6.ts line-for-line.
1. Background: Why a New Scoring Framework Was Necessary
A new scoring framework was necessary because AI answer engines choose the pages they cite by different rules from the ones search engines use to rank pages.
1.1 The Measurement Problem with AI Search
The transition from keyword-ranked search to AI-synthesized search creates a measurement problem that existing SEO tools were not designed to solve.
Traditional SEO tools measure what they can observe: crawlability, link graphs, keyword occurrence, page speed, structured data presence. These are valid measurements. But they were designed to predict performance in a system where the scoring entity - Google's ranking algorithm - values these signals for specific, well-documented reasons.
AI citation engines do not operate on the same scoring logic. A language model deciding whether to cite a page in a synthesized answer is not running a PageRank calculation. It is doing something closer to information extraction: it is asking whether the page contains a clean, attributable, structurally accessible answer to the query it is processing. The signals that predict success in that process overlap with traditional SEO signals - but they are not the same set.
The core difference is this: traditional SEO is optimized for retrieval. GEO is optimized for extraction. A search engine retrieves the most relevant pages. An AI citation engine extracts the most useful content from the pages it can read.
This distinction drives the entire GeoTest Scoring Engine design. Every category, every signal, every scoring decision traces back to one question: can an AI agent find, read, parse, and extract a citable answer from this page?
1.2 What Existing Research Established
Before designing the scoring framework, we reviewed the available research on AI citation behavior and zero-click search trends.
Chartbeat's analysis of traffic patterns across more than 2,500 publisher websites found Google search referral traffic down 33% globally and 38% in the US year-over-year as of early 2026[1] - measured before Google I/O's agentic search announcements accelerated the shift.[9] The impact is not uniform: publishers with fewer than 10,000 daily pageviews have absorbed a 60% decline; mid-sized publishers are down 47%.[6]
Similarweb's tracking of zero-click searches - queries where the user never clicks any result - shows the rate rising from 56% to 69% between May 2024 and May 2025.[2] When Google's AI Overviews surface on a results page, 83% of searches end without a click. In Google's AI Mode, that figure reaches 93%.[5]
A Pew Research Center study analyzing 68,000 real search queries found that users clicked on results 8% of the time when an AI summary appeared, compared to 15% without one - a 47% reduction in click probability from a single UI change.[3]
Buyers have moved with it: in G2's The Answer Economy research (March 2026), 71% of B2B software buyers rely on AI chatbots for software research.
These numbers establish the stakes. They do not, by themselves, tell us which sites get cited in AI-generated answers and which do not. That required direct observation across a large enough site sample to identify patterns.
1.3 How the Framework Was Built
The GeoTest framework was built from a structured observation process across the client and benchmark sites in our analysis network. We ran queries against Google AI Overviews, Gemini, ChatGPT, and Perplexity, tracked which pages were cited, and reverse-engineered the structural properties of cited pages versus non-cited pages in the same category and competitive set.
The patterns that emerged consistently enough to build a scoring category around were:
- Pages with valid structured data (JSON-LD) were cited at significantly higher rates than structurally identical pages without it, controlling for content quality
- Pages with FAQPage schema were cited in response to question-format queries at rates that outperformed higher-ranked pages without schema
- Pages that stated concrete facts (numbers, prices, dates, named sources) were cited far more often than longer pages that described the same topic in general terms; our own early reading of this as a word-count effect was corrected by the 2026 studies cited in section 2.1
- Pages that loaded content via client-side JavaScript were frequently extracted as empty or partial by agent crawlers, eliminating them from citation consideration
- Off-site brand mentions - in Reddit threads, LinkedIn posts, podcast transcripts, and Wikipedia - correlated more strongly with AI citation frequency than traditional backlink profiles
These observations shaped the six categories of the GeoTest Scoring Engine and their relative weight in the total score.
2. The Six-Category Framework (v6.0)
The GeoTest Scoring Engine's six-category framework scores in two layers. Every page is scored across six categories for a page score out of 100, the same function whether the page is scanned alone or as part of a crawl. A site crawl adds a site layer out of 100 for what only a crawl can prove, and the site score is 70% the weighted page average plus 30% the site layer. A single-page scan cannot prove the site layer, so its headline earns that 30% only in proportion to how much of the 100-point rubric the page could be tested on: page score × (0.70 + 0.30 × points tested ÷ 100).
The six page-layer categories, with their exact point weights as implemented in the production engine (v6.0), are below; every sub-check, cap and example is also set out on the GEO Score rubric page:
| # | Category | Weight | What it answers |
|---|---|---|---|
| 1 | Citation Worthiness | 34 pts | Does this page carry facts an answer engine can quote, and show where they came from? |
| 2 | Answer Structure | 22 pts | Can an engine lift a complete, self-contained answer from this page without reading all of it? |
| 3 | Authority and Trust | 17 pts | Can an engine tell who is behind this page, how to reach them and who vouches for them? |
| 4 | Structured Data | 12 pts | Is the page's meaning declared in a form a machine can read, and does it match what the page says? |
| 5 | Freshness | 7 pts | Can an engine date this page, and does the date hold up? |
| 6 | Extractability | 8 pts | Can a crawler reach the page, read its text in the first response and know which URL is the original? |
| Total | 100 pts | No bonuses; gates and penalties act as absolute caps |
2.1 What changed from v4.0 to v5.0
What changed in v5.0 was where the points went: v4.0 gave 25 points to Content Quality, most of it to word count against a per-type depth target, and 18 to Structured Data. Neither weight had empirical provenance. Two large studies published since point the other way. Ahrefs, across 560,346 AI Overviews and 174,048 cited pages, found no advantage for long pages. Stacc, across 57,253 URLs and 1.85 million fact appearances, found pages with 12.5 or more facts per 1,000 words were 4.2 times more likely to be cited. Semrush, across five million cited URLs, found Organization schema on only 25% to 34% of cited pages.
So v5.0 moved the points. Length stopped scoring and only gated (under 150 body words capped the page at 40, 150 to 300 at 70). Citation Worthiness rose to 34 and gained three checks: coverage of the facts that currently-cited pages agree on, attributed quotations, and a weighted external-citation count. Answer Structure (22) replaced FAQ and Q&A Format and added the check that sections open with the answer. Structured Data fell to 12. Freshness became its own category (7) with a machine-readable date agreement check. Extractability (8) is Crawler Accessibility renamed. The v4 penalty that silently suppressed fact density on health, legal and financial sites was removed; on those verticals only sourced figures counted. v6.0 keeps these six category weights and changes what happens inside them, set out in section 2.4.
Stored results are never rescored. Every report keeps the version it was produced under, and the version is printed on the score card, so a v4.0, v5.0 or v6.0 number is never compared to a number from another version as if they were the same scale.
| Score Range | Grade | Interpretation |
|---|---|---|
| 90–100 | A · EXCELLENT | Optimized for AI citation across all measurable dimensions |
| 80–89 | B · GOOD | Strong citation presence with a few gaps left to close |
| 65–79 | C · FAIR | Competitive citation presence; incremental improvements compound |
| 50–64 | D · MODERATE | Extractable but lacking signals that drive active citation |
| 35–49 | E · POOR | Structural barriers prevent consistent citation |
| 0–34 | F · CRITICAL | AI agents cannot reliably extract content from this site |
2.2 Caps
Caps are absolute ceilings: while a cap's trigger is present, the page or site cannot score above it, whatever the categories add up to.
- Page: This page is set to noindex, capped at 30. A noindex tag in the page or in an X-Robots-Tag header caps the page at 30 until it is removed.
- Page: Under 150 words of main content, capped at 40. A page with fewer than 150 words of main content has little to quote. This applies to articles, documentation, product, case study and about pages, not to short pages such as contact and legal.
- Page: 150 to 299 words of main content, capped at 70. A short page can still be dense and well structured, but it cannot score above 70. The same page types apply.
- Page: Placeholder or Lorem copy detected, capped at 50. Lorem ipsum, or three or more unfinished-site phrases, mean the page is unfinished. It is capped at 50 until the copy is real.
- Site: robots.txt disallows all crawlers, or blocks Googlebot or Bingbot site-wide, capped at 30. If the main search crawlers cannot read the site, the site layer and the site score cannot rise above 30.
- Site: Two or more AI search-indexing crawlers blocked, capped at 70. Blocking two or more of OAI-SearchBot, PerplexityBot and Claude-SearchBot, site-wide or on substantive paths, caps the site layer and site score at 70. User-triggered fetchers and training crawlers are reported but never penalized.
2.3 The site layer
A Site Analysis adds a second 100-point layer for what only a crawl can prove. It is weighted 30% in the site score and is reported as "not tested" on a single-page scan, such as one from the free GEO Score checker, rather than scored as a failure.
- Topical cluster depth (12 pts). Groups of three or more substantive pages that share two or more terms from their titles, H1s or URL slugs, with two or more contextual links between them and no pair mostly duplicated. Three clusters earn 12; two earn 8; one earns 4.
- About or Team page (10 pts). A page found by URL, title or AboutPage schema with 100 or more words about the organization. 10, or 5 if thin.
- Entity completeness (10 pts). Organization JSON-LD with name and URL (2), a logo (2), two or more profile links that resolve and match the brand (2), a contact point or address (2), and a founding date or founder (2). Capped at 6, with a flag, if the schema name, the visible brand, the hostname and the profiles disagree.
- robots.txt allows search-indexing crawlers (10 pts). 2 points for each of the five search-indexing crawlers (Googlebot, Bingbot, OAI-SearchBot, PerplexityBot, Claude-SearchBot) that is allowed, 1 if allowed at the root but blocked on substantive paths, 0 if blocked. A robots.txt that cannot be read is unknown, not blocked.
- Page breadth (8 pts). Substantive pages (indexable, canonical, 150 or more words, not tag, utility or legal pages): 10 or more earns 8, 5 earns 5, 3 earns 3.
- Q&A surface (8 pts). Any help, FAQ or knowledge-base page, any page with five or more question-and-answer pairs, or FAQPage markup with five or more visible questions. No /faq path is required.
- sitemap.xml present, healthy and complete (8 pts). Exists and parses (3), 90% or more of its URLs return 200 and are indexable and canonical (3), and it covers 80% or more of the crawled substantive pages (2).
- Site-wide fact density (7 pts). The median fact density of editorial pages: 12.5 per 1,000 words earns 7, 8 earns 5, 5 earns 3, 2 earns 1.
- Cross-page schema consistency (7 pts). Organization on the homepage (3), valid JSON-LD on half or more of inner pages (2), and no conflicting entity names or URLs across pages (2).
- Internal link health (6 pts). Orphaned substantive pages at 10% or fewer (3), and no broken internal links (3).
- Site Q&A depth (5 pts). Unique question-and-answer pairs across the site: 15 or more earns 5, 8 earns 3, 3 earns 1.
- Contact surface (5 pts). A contact page that returns 200, or two or more contact methods across the site.
- Privacy and Terms pages (4 pts). Privacy and terms both crawled and returning 200 after redirects (HTML or PDF). One combined policy counts as both; one document earns 2.
- llms.txt (reported, not scored) (0 pts). Reported as a recommendation. It carries no points until citation data shows it matters.
2.4 GEO v6.0 and the v5.0 history
GEO v6.0 is the current engine, and v5.0 is kept below as history: its scores stay archived under their own version and are never compared with v6.0 scores.
What the score measures. How reliably a site exposes useful, attributable, structured and technically accessible information to search engines and AI retrieval systems. It does not measure business quality, rankings, traffic, or guaranteed AI citation. Crawler access raises eligibility; it does not guarantee inclusion in any AI answer.
v6.0 keeps the six page categories and the 70/30 roll-up of page average and site layer. It changes how things are detected and how the weights are spent.
- Detection. Presence checks (social proof, byline, Q&A, contact, legal links and others) read schema first, then page structure, then narrow language, and finally an AI second opinion on anything still absent. The AI can only raise an absent result, only with a quote that GeoTest verifies is on the page. Counts, densities and technical checks keep their own fixed rules.
- Four result states. Present, absent, not applicable and unknown. Unknown means we could not read the page reliably (a failed render, a bot wall, a file that did not answer). It leaves the total and is never shown to you as a missing element.
- Coverage beside the score. Every report states how much of the expected evidence was evaluated. A single page under 75% coverage shows Insufficient coverage instead of a grade; a site score under 75% is labelled provisional.
- Page-type applicability. A homepage is not scored on bylines; a legal page is not scored on social proof, Q&A or length and leaves the page average; contact and location pages count for half. A link to /faq or /about no longer passes a page-level check.
- Rendered content. Content that appears only after JavaScript runs counts as present and is flagged as an extraction risk, scored under Rendered parity in Extractability and never under the content check itself.
- Crawlers. Only search-indexing crawlers (Googlebot, Bingbot, OAI-SearchBot, PerplexityBot, Claude-SearchBot) are scored. User-triggered fetchers and training crawlers are reported and never penalized. A robots.txt that cannot be read is unknown, not blocked.
- Rebalanced weights. Q&A surface and depth fall from 23 to 13 site points, robots.txt from 15 to 10, and llms.txt leaves the score. Answer openings and entity completeness rise. The free Article points on non-blog pages and the double weight for .gov and .edu links are removed, and social proof is graduated (3 for one kind of evidence, 5 for two).
- Evidence on every pass. Each result carries the snippets and locations that earned it, shown in your report, and each scan stores the detector, content extractor, crawler registry, model and prompt versions it was produced under.
The v5.0 category weights, kept for archived reports: Citation Worthiness 34, Answer Structure 22, Authority and Trust 17, Structured Data 12, Freshness 7, Extractability 8. The six v6.0 categories carry the same maximums.
3. Citation Worthiness — 34 pts
Citation Worthiness is worth 34 of the 100 page-layer points.
3.1 What this category answers
The category answers one question: does this page carry facts an answer engine can quote, and show where they came from?
Answer engines cite the page that supplies the number, the definition or the named source. v6.0 separates facts that are sourced (a link, a citation or an attribution next to the figure) from facts that are only stated, because a figure with a source can be checked and quoted with confidence.
3.2 What we measure
The engine runs 7 checks to measure Citation Worthiness, each with its points:
- Sourced facts per 1,000 words (8 pts). Specific facts (percentages, counts with units, money, measurements, dated events) with a link, a citation or an attribution phrase within 200 characters. Marketing claims such as 'up to', superlatives and adoption counts are not facts. 5 per 1,000 words earns 8; 3 earns 6; 2 earns 4; 1 earns 2.
- Fact density per 1,000 words (4 pts). All specific facts, sourced or not. 12.5 or more earns 4; 8 earns 3; 5 earns 2; 2 earns 1. Copyright years, navigation and footer text and prices outside product pages are not counted.
- Topic fact coverage (8 pts). The share of the facts that currently-cited pages for this page's topic agree on that this page also states. 40% earns 8; 30% earns 6; 20% earns 3; 10% earns 1. Not tested when no claim set exists, and then left out of the denominator.
- Attributed quotations (5 pts). A blockquote, <q>, figure with a caption or a quoted span of ten words or more, with a citation, an attribution verb or a person or organisation name beside it. Three earn 5; two earn 3; one earns 2.
- External source citations (5 pts). Unique outbound links in the main content placed next to a factual claim. 6 earns 5; 4 earns 4; 2 earns 2; 1 earns 1. Your own domain and social profiles do not count, and .gov, .edu and .org links are not weighted extra.
- Comparison table or grid (2 pts). A real table with header cells and two or more data columns, or an aligned comparison grid of two or more items sharing three or more labelled attributes. Layout tables do not count.
- Quotable definitions (2 pts). A <dfn>, a definition list, 'X is a ...' under a heading about X, or 'defined as', 'refers to' or 'means'. Three or more earn 2; one or two earn 1.
3.3 Example
An example that fails, and one that scores:
Fails: <p>Our service is trusted by thousands and delivers up to 10x better results.</p>
Scores: <p>Median delivery time fell from 9 days to 3 days across 412 orders in 2025, according to the <a href="https://example.org/report">carrier's annual report</a>.</p>
The second version states figures and links the source beside them, so each can be verified and quoted. The first makes claims that are excluded from the count.
3.4 What to do
- Replace adjectives and 'up to' claims with figures, and put the source in the same sentence.
- Link each statistic to its primary source.
- Quote named people or organisations, in their own words, with the attribution beside the quote.
- Add one real comparison table and a clear definition for each main term.
4. Answer Structure — 22 pts
Answer Structure is worth 22 of the 100 page-layer points.
4.1 What this category answers
The category answers one question: can an engine lift a complete, self-contained answer from this page without reading all of it?
Retrieval works section by section. The score rewards sections that answer their own heading, passages that name their subject so they make sense when quoted alone, and Q&A that is visible on the page in whatever form your site uses, not only in one /faq path.
4.2 What we measure
The engine runs 6 checks to measure Answer Structure, each with its points:
- Self-contained answer openings (8 pts). The share of H2/H3 sections whose first sentence is at least 8 words, has no preamble ('In this section', 'Let's look at') and shares a term with its heading. 80% earns 8; 60% earns 6; 40% earns 4; 20% earns 2.
- Heading hierarchy (4 pts). Exactly one H1 (+2), and enough H2 sections for the length of the page (one per 400 words, at least one) with no skipped levels (+2; +1 if there are some H2s but fewer).
- Q&A block on this page (4 pts). FAQPage or QAPage schema backed by visible text, or three or more question-and-answer pairs from accordions, definition lists or headings with answers of 15 words or more. Outside a section or page labelled FAQ, questions or help, a heading counts only if it ends with a question mark. 3+ pairs earn 4; 1 to 2 earn 2.
- Question depth on this page (2 pts). Unique question-and-answer pairs: 8 or more earns 2; 4 or more earns 1.
- FAQPage JSON-LD backed by visible text (2 pts). Valid FAQPage markup where at least half the questions appear as visible text. Markup with no visible Q&A scores 0 and is flagged.
- Self-contained passages (2 pts). Sections of 40 to 300 words that name their subject instead of opening with It, This or They. 70% earns 2; 40% earns 1.
4.3 Example
An example that fails, and one that scores:
Fails: <h2>Pricing</h2><p>It starts with a free plan, and this scales as they grow.</p>
Scores: <h2>How much does Acme Billing cost?</h2><p>Acme Billing costs $29 a month for up to 500 invoices, and a free plan covers 20 invoices a month.</p>
The opening sentence of the second section names the product, answers the heading and carries the figures, so it still works when an engine quotes it alone.
4.4 What to do
- Rewrite the first sentence under each heading so it answers the heading and names its subject.
- Show questions and answers as visible text, and mirror them in FAQPage markup only if you do.
- Use one H1 and enough descriptive H2s for the length of the page.
5. Authority and Trust — 17 pts
Authority and Trust is worth 17 of the 100 page-layer points.
5.1 What this category answers
The category answers one question: can an engine tell who is behind this page, how to reach them and who vouches for them?
These signals are now read from how the page is built, not from single words. A testimonial is recognised by its structure (a quote with a named person or company beside it), a byline by its position and markup, and contact details by working methods, not the word 'street'.
5.2 What we measure
The engine runs 5 checks to measure Authority and Trust, each with its points:
- Social proof (5 pts). Evidence of six kinds: an attributed testimonial (a quote with a named person or company in the same block); a rating or review shown on the page or in Review or AggregateRating schema backed by a visible rating; a customer logo row of three or more named marks; a case study or result naming a customer; independent recognition (an award, accreditation, certification or a press row); or an adoption count of 100 or more. One kind earns 3; two or more earn 5. Legal pages never qualify.
- Author byline (4 pts). A person author in JSON-LD, rel=author, a meta author tag or an author box, or 'written by' or 'reviewed by' with a name near the start or end of the main content. A name alone earns 2; with a role, credentials or an author page link, 4. Names in comments, related-post cards and sidebars do not count.
- Contact methods (3 pts). On-page ways to reach you: a tel: link, a mailto: link, telephone, email, contact point or address in schema, or a working contact form. Two or more earn 3; one earns 2; a link to a contact page alone earns 1.
- Privacy and Terms links (2 pts). Footer or navigation links to privacy and terms that resolve to a live page (HTML or PDF). One combined policy covering both earns 2; one earns 1.
- Contextual internal links (3 pts). Links in the main content to indexable live pages with descriptive anchor text. On pages under 500 words one link earns 3; otherwise 3 or more earn 3 and one or two earn 1.
5.3 Example
An example that fails, and one that scores:
Fails: <p>Great service!</p> <p>Posted by John Smith in the comments.</p>
Scores: <blockquote><p>Saved our yard 20 hours a week.</p><footer>Mike D., Columbus, Ohio</footer></blockquote>
A quote with a named person beside it is recognised as an attributed testimonial without needing a keyword such as 'testimonial' or 'review'.
5.4 What to do
- Put a real name and a role beside every testimonial, in the same block as the quote.
- Show a visible rating if you publish Review or AggregateRating markup.
- Put a named author with a role on articles, near the top or the end.
- Give at least two working ways to reach you on every non-legal page.
6. Structured Data — 12 pts
Structured Data is worth 12 of the 100 page-layer points.
6.1 What this category answers
The category answers one question: is the page's meaning declared in a form a machine can read, and does it match what the page says?
Schema states what a page is and who published it. The score checks that the type fits the page, that the required properties are present, and that names, ratings, prices and dates agree with the visible text. Every page type is held to the schema that fits it.
6.2 What we measure
The engine runs 6 checks to measure Structured Data, each with its points:
- Primary schema type matches the page (4 pts). The JSON-LD type fits the page type: Organization or WebSite on the homepage, Article or BlogPosting on articles, Product, Service or SoftwareApplication on product pages, FAQPage on FAQ pages, LocalBusiness on location pages, and so on.
- JSON-LD parses (1 pts). Every JSON-LD block is valid.
- Schema properties present and agree with the page (1 pts). The required properties for each type are present, and names, ratings, prices and dates match the visible text.
- BreadcrumbList (1 pts). BreadcrumbList on inner pages.
- Supporting schema types (1 pts). Review, AggregateRating, Person, HowTo or ItemList where the page has that kind of content. Not applicable when it does not.
- Meta description + OG + Twitter card (4 pts). A meta description of 80 to 200 characters, Open Graph title and description, and a Twitter card.
6.3 Example
An example that fails, and one that scores:
Fails: <script type="application/ld+json">{"@type":"Organization"}</script>
Scores: <script type="application/ld+json">{"@type":"Organization","name":"Acme","url":"https://acme.example"}</script>
The second block carries the required name and URL. The first is valid JSON but has nothing in it a machine can use.
6.4 What to do
- Emit the schema type that matches each page type from your templates.
- Make sure every ratings, price and date value in schema is also visible on the page.
- Fill the meta description, Open Graph and Twitter card on every page.
7. Freshness — 7 pts
Freshness is worth 7 of the 100 page-layer points.
7.1 What this category answers
The category answers one question: can an engine date this page, and does the date hold up?
Dates matter for articles, documentation and product pages with prices or specifications. Pages that are not expected to carry a date are not scored on it.
7.2 What we measure
The engine runs 2 checks to measure Freshness, each with its points:
- Recency of last update (5 pts). A visible date labelled updated, modified or reviewed, then JSON-LD dateModified, then the sitemap's lastmod. Within 3 months earns 5; 6 months 3; 12 months 1. A date known only from the sitemap earns at most 3. Documentation with a last-reviewed date or version marker within 12 months earns 5.
- Machine-readable date agreement (2 pts). dateModified within 7 days of a visible date earns 2; a schema date with no visible date earns 1; a mismatch earns 0.
7.3 Example
An example that fails, and one that scores:
Fails: <p>Updated recently.</p>
Scores: <p>Last updated 14 September 2026</p><script type="application/ld+json">{"@type":"Article","dateModified":"2026-09-14"}</script>
A visible date and a matching dateModified in the same week, so the date can be trusted.
7.4 What to do
- Show a 'Last updated' date on articles, docs and product pages, using the real edit date.
- Keep dateModified in schema within a week of the visible date.
8. Extractability — 8 pts
Extractability is worth 8 of the 100 page-layer points.
8.1 What this category answers
The category answers one question: can a crawler reach the page, read its text in the first response and know which URL is the original?
If a page is noindexed no amount of content helps, and a noindex caps it at 30. v6.0 also compares the text in the initial HTML with the text after JavaScript runs: content that exists only after rendering counts as present but is flagged as an extraction risk here, never as missing content.
8.2 What we measure
The engine runs 4 checks to measure Extractability, each with its points:
- Not noindex (3 pts). No noindex in a meta robots tag or an X-Robots-Tag header.
- Rendered parity (2 pts). The share of the page's rendered main-content words already present in the initial HTML. 90% earns 2; 60% earns 1.
- Canonical tag (2 pts). Present, absolute, resolves to a live indexable page and matches the page or the sitemap URL. A canonical with a problem earns 1.
- Mobile viewport meta (1 pts). A viewport meta tag.
8.3 Example
An example that fails, and one that scores:
Fails: <div id="root"></div><script src="app.js"></script>
Scores: <main><h1>Mobile IV hydration</h1><p>...</p></main>
The text is in the first response, so crawlers that do not run JavaScript still read it.
8.4 What to do
- Remove noindex from every page you want cited.
- Server-render or pre-render public pages.
- Point the canonical at the page's own live address.
9. The AI Visibility Testing Protocol
Beyond the six structural scoring categories, we include an AI visibility test in every GEO audit. This is a direct observation process: we run a defined set of queries through Perplexity and Gemini and record whether the client site is cited.
9.1 Query Selection
We construct three to five test queries per audit, drawn from two sources:
- Category-defining queries. These are the highest-frequency, highest-value queries in the client's category - the searches that represent primary business intent. For a ground protection mat supplier, a category-defining query might be 'who supplies construction access mats in Texas.' For a payment processor, it might be 'best payment processor for small restaurants in New Orleans.'
- Feature-specific queries. These test whether particular differentiators or claims the client makes are surfacing in AI answers. For a moving broker with federal licensing, we would test 'FMCSA licensed moving brokers.' For a payment platform with a specific integration, we would test the integration by name.
9.2 What We Record
For each query, we record:
- Whether the client site was cited (yes/no)
- Which competitors were cited instead
- The structural characteristics of the cited pages (schema presence, content depth, FAQ coverage)
- A hypothesis about why the cited page won and the client page did not
This last element - the structural analysis of winning pages - is often the most actionable output of the entire audit. It converts abstract scoring into concrete competitive intelligence: here is exactly what the cited competitor has that you do not.
9.3 Interpreting Non-Citation
Non-citation in the AI visibility test does not always indicate a content quality problem. The most common causes of non-citation, in order of frequency across our audit set:
- Schema absence - the page has no machine-readable identity or content structure signals
- Rendering failure - the page content is delivered via client-side JavaScript and is partially or fully invisible to the crawler
- Content below threshold - the page is too thin to constitute a citable source
- Geographic/topical mismatch - the page does not contain the specific geographic or topical signals the query requires
- Off-site authority deficit - the domain has insufficient cross-platform presence for the AI to treat it as an established source
Each cause has a different remediation path, and identifying the correct cause is essential to prescribing the correct fix.
10. Scoring, Reporting, and the Projection Framework
Scoring turns each check into points, and reporting adds a projection of the score once the recommended fixes are made.
10.1 From Signals to Scores
The GeoTest Scoring Engine converts the observations from each category into a numerical score using the weighted model published in §2 above. The exact weights in v6.0 - Citation Worthiness 34, Answer Structure 22, Authority and Trust 17, Structured Data 12, Extractability 8, Freshness 7 - follow the citation evidence set out in §2, not theoretical importance. (In v4.0 they were Content Quality 25, Citation Worthiness 20, Structured Data 18, Authority Signals 17, FAQ & Q&A Format 12, Crawler Accessibility 8; reports scored then keep those weights.) Signals that consistently predict citation win more weight than signals that seem important but do not discriminate between cited and non-cited pages in practice.
What we do publish is the interpretive principle: weights follow the published citation studies in §2, not our own correlation data and not theoretical importance. A signal those studies tie to citation wins more weight than a signal that seems important but has not been shown to separate cited from non-cited pages.
The result is a structured readiness score, not a prediction. A higher score means a page has more of the features those studies link to citation; it does not guarantee that any engine will cite it. The live AI citation test in §9 is how you check what the engines actually do, and the GEO Score benchmark shows where public sites land on this scale, most recent scan per site.
10.2 The Score Projection Model
Every GEO audit includes a score projection: what the site's score would be if the recommended improvements were implemented. The projection reruns the scoring engine with the recommended fixes applied, so caps and the checks that apply to each page type are accounted for. There is no multiplier and no ceiling.
This is intentionally conservative. We project only to the score achievable through the specific recommendations in the report - we do not project to a theoretical maximum or include speculative improvements. A site scoring 50 with a projection of 74 means: implement these specific, scoped actions and we expect the score to reach approximately 74.
Score projections have two practical uses: they prioritize action sequencing (the actions with the highest score delta per implementation hour should be done first) and they provide a baseline for measuring improvement over time.
10.3 Re-Audit and Verification
A re-audit is needed because GEO scores are not permanent. Schema implementations can break. Content can decay in freshness. Competitors can improve their own citation profiles, changing the relative dynamics in a category. We recommend re-auditing on a 90-day cycle for sites in active improvement phases and a 180-day cycle for sites in maintenance.
The re-audit is not a new baseline - it is a measurement of delta from the previous audit. Sites that implement our recommendations reliably show measurable score improvement within 60 to 90 days, consistent with the crawl and index cycles of the major AI platforms.
11. Limitations and Known Boundaries of the Framework
Scientific rigor requires acknowledging what the framework does not measure and where its predictions are less reliable.
- We cannot observe AI model internals. The GeoTest Scoring Engine is an observational model, not an access-based model. We can observe what gets cited; we cannot observe the internal decision logic of any specific AI system. The framework predicts citation outcomes based on observed structural patterns - it does not claim to reverse-engineer any proprietary model.
- Category weights are empirically derived and subject to change. As AI search systems evolve and as our observation dataset grows, the relative importance of different signals will shift. The current weighting reflects patterns observed through early 2026.
- Off-site authority is the hardest dimension to score precisely. Authority and Trust (section 5) and the off-site brand presence dimension are the scoring areas with the least direct measurement access. We use observable proxies - bylines with credentials, attributed social proof, Organization schema and the profiles it links to - but the full picture of a domain's authority across the AI citation graph is not fully observable from a site audit.
- Scores reflect AI citation potential, not guaranteed traffic outcomes. A score of 85 does not guarantee AI citation. It indicates that the structural conditions for citation are well-established. Whether a site is actually cited depends on the competitive set, query specifics, and the content of individual AI interactions, which are variable.
12. Conclusion
In conclusion, the shift from search engine optimization to generative engine optimization is not a trend to watch. For mid-market businesses that depend on digital discovery, it is the operational reality of the second half of 2026 and beyond. The measurement infrastructure for this new environment is what the GeoTest Scoring Engine was built to provide.
The framework we have described in this document - six categories, 100 points, direct observation of AI citation behavior, schema validation, fact density and sourcing, answer structure analysis, and authority signal evaluation - represents our current best model of what predicts AI citation success. It is empirical, not theoretical. It is updated when the data changes. It produces actionable, prioritized recommendations rather than abstract scores.
For businesses operating in this environment, the most important thing to understand about GEO scoring is that it is not difficult to improve. The sites that score lowest are almost universally not sites with bad content - they are sites with good content that was never prepared for machine extraction. Adding schema, restructuring headings, implementing FAQPage markup, expanding thin pages, and fixing rendering issues are engineering and content tasks, not fundamental business changes. They are achievable within a single quarter.
The sites that do this work in 2026 will be the default citation sources for their categories by the time their competitors notice the rules have changed.
Appendix A: Schema Types Referenced in This Document
- Organization schema - Declares business identity, address, contact information, and social profiles. The foundational schema type for any business website.
- LocalBusiness schema - Extends Organization for geographically located businesses, adding serviceArea, openingHours, and priceRange fields.
- FAQPage schema - Wraps question-and-answer pairs in machine-readable markup. Quick to add, and it counts only when the questions and answers are also visible on the page.
- Article schema - Declares editorial content with author, publication date, and modification date. Enables recency signals and author attribution.
- HowTo schema - Structures instructional content as steps, so an engine can read the steps in order.
- Product schema - Declares product attributes including name, description, SKU, price, and availability. Essential for e-commerce and product specification pages.
- Person schema - Declares individual credentials, role, and organizational affiliation. Critical for E-E-A-T and author attribution.
- AggregateRating schema - Structures review data with rating value and review count. Cited in AI responses to quality and comparison queries.
- BreadcrumbList schema - Declares the navigational path to a page. Enables multi-page citation chains and helps AI agents map site structure.
Appendix B: Sources and References
Each source below is numbered to match the bracketed references in the text.
- [1]Chartbeat (2026). Global publisher Google search referral traffic analysis, 2025–2026. via AdExchanger.
- [2]Similarweb (2025). Zero-click search data, May 2024 to May 2025. via Search Engine Journal.
- [3]Pew Research Center (2025). Analysis of 68,000 real search queries: AI summary click behavior. Pew Research.
- [4]Gartner (2026). Search volume projection, 2026. Gartner Research.
- [5]ALM Corp (2025). AI Overviews 58% CTR reduction analysis. ALM Corp Blog.
- [6]AdExchanger (2026). The AI Search Reckoning Is Dismantling Open Web Traffic. AdExchanger.
- [7]Schema.org (n.d.). Structured data vocabulary reference. Schema.org.
- [8]Google Search Central (2024). Introduction to structured data. Google Developers.
- [9]Google (2026). Google Search's I/O 2026 updates: AI agents and more. The Keyword.
- [10]The Verge (2026). Google Search is getting its biggest changes ever. The Verge.
About the author
The author, Jason Gordon, is Founder & CEO of SpecLoop and GeoTest.ai. He built the GeoTest scoring engine and leads GEO strategy for SpecLoop's client engagements. He publishes The GEO Report, a weekly newsletter on AI, software strategy, and Generative Engine Optimization.
Methodology FAQ
The methodology questions below are answered from the rubric and the studies on this page.
What is a GEO score?+
A GEO score is a 100-point measurement of a website's readiness to be cited by AI-powered search engines like Google AI Overviews, ChatGPT, Gemini, and Perplexity. The GeoTest Scoring Engine evaluates six categories: Citation Worthiness, Answer Structure, Authority and Trust, Structured Data, Freshness, and Extractability. Scores are interpreted on a six-level scale: EXCELLENT (90 to 100), GOOD (80 to 89), FAIR (65 to 79), MODERATE (50 to 64), POOR (35 to 49), and CRITICAL (0 to 34). In audits scored before v6.0, most mid-market business websites scored between 45 and 65: functional sites with real content that were structurally invisible to AI citation engines because they were built for a search paradigm that no longer applies.
What is the difference between SEO and GEO?+
SEO (Search Engine Optimization) is optimized for retrieval - getting a page ranked highly so users click through to it. GEO (Generative Engine Optimization) is optimized for extraction - ensuring AI agents can find, read, parse, and cite specific content from a page when generating synthesized answers. A page can rank #1 on Google and never appear in an AI-generated answer. Conversely, a page on page two can become a primary AI citation source if its content is structured with schema markup, answer-first architecture, and sufficient depth. Traditional SEO was designed to predict performance in a ranking system. GEO is designed to predict performance in a content extraction system.
Why does FAQPage schema improve AI citation rates?+
FAQPage JSON-LD schema wraps each question-answer pair in machine-readable markup, making it directly extractable by AI agents without requiring them to parse unstructured prose. When an AI agent processes a question-format query - the dominant mode of AI search - it scans indexed content for FAQPage schema and preferentially extracts answers from those pages over equivalent unstructured content. For most business websites it is also one of the quickest schema types to add. A single FAQ page with valid schema, specific answers of 75 words or more, and questions aligned to actual user queries can generate AI citations across dozens of related queries.
Why isn't my website being cited by AI search engines?+
The five most common causes of non-citation, in order of frequency, are: schema absence (no machine-readable identity or content structure), rendering failure (page content delivered via client-side JavaScript and invisible to AI crawlers), fact-thin content (pages that describe a topic without stating numbers, prices, dates or named sources give the engine nothing to quote), geographic or topical mismatch (the page lacks the specific signals the query requires), and off-site authority deficit (the domain has insufficient cross-platform presence for AI systems to treat as an established source). Each cause has a different remediation path. Identifying the correct cause through a structured audit is essential before prescribing fixes - the same symptom can have multiple root causes with completely different solutions.
Is there a minimum word count for AI citation?+
Not as a score. Length has earned no points since Scoring Engine v5.0, and v6.0 keeps it that way; what earns points is sourced facts and the density of facts, coverage of the facts other cited pages agree on, attributed quotations and sections that open with the answer. Two gates remain on articles, documentation, product, case study and about pages, because a page with almost nothing on it has nothing to quote: under 150 words of main content caps the page at 40, and 150 to 299 words caps it at 70. Short pages such as contact and legal pages are not gated. From 300 words up, a dense page beats a padded one.
How long does it take to improve a GEO score?+
Sites that implement GeoTest recommendations reliably show measurable score improvement within 60 to 90 days, consistent with the crawl and index cycles of the major AI platforms. The fastest improvements come from schema implementation (FAQPage, Organization, Article), fixing JavaScript rendering failures, and adding missing H1 tags - all completable within days, with citation impact within weeks. Content depth improvements take longer to index and compound. We recommend re-auditing on a 90-day cycle for sites in active improvement phases to track score delta against the baseline. A site that implements the full recommendation set from a GeoTest audit typically moves from the MODERATE range into the GOOD range within a single quarter.
Quick answers
All answers →
The checks an answer engine runs before it cites a page, as a list you can work through on your own site.
Run the rubric on your own page. Then get the fix.
Free Quick Scan of one page, about 15 seconds. No credit card. Paid plans write the fixes.